testing lift media to catbox
This commit is contained in:
 ed committed
1 parent
dcb4ac4a72
commit
f156455ec7
7 files changed
+1017
-14
No files matched your search
+31
-7
@@ -1,11 +1,11 @@
|
||||
---
|
||||
title: "The subpix version is definitely better."
|
||||
title: "SPC: CRT shader on the Deck."
|
||||
type: archive
|
||||
source: twitter
|
||||
source_url: "https://x.com/NOTimothyLottes/status/1692565070583136348"
|
||||
source_url: "https://x.com/NOTimothyLottes/status/1692559239116406864"
|
||||
author: "NOTimothyLottes"
|
||||
handle: NOTimothyLottes
|
||||
post_id: "1692565070583136348"
|
||||
post_id: "1692559239116406864"
|
||||
date: 2023-08-18
|
||||
archived: 2026-08-23
|
||||
status: draft
|
||||
@@ -14,20 +14,44 @@ tags:
|
||||
- archive
|
||||
- twitter
|
||||
- NOTimothyLottes
|
||||
description: "The subpix version is definitely better."
|
||||
description: "SPC: CRT shader on the Deck."
|
||||
in_reply_to: ""
|
||||
---
|
||||
|
||||
## Source
|
||||
|
||||
- URL: https://x.com/NOTimothyLottes/status/1692565070583136348
|
||||
- URL: https://x.com/NOTimothyLottes/status/1692559239116406864
|
||||
- Author: NOTimothyLottes (@NOTimothyLottes)
|
||||
- Posted: 2023-08-18 15:52:13
|
||||
- Posted: 2023-08-18 15:29:03
|
||||
|
||||
## Thread
|
||||
|
||||
**1/**
|
||||
|
||||
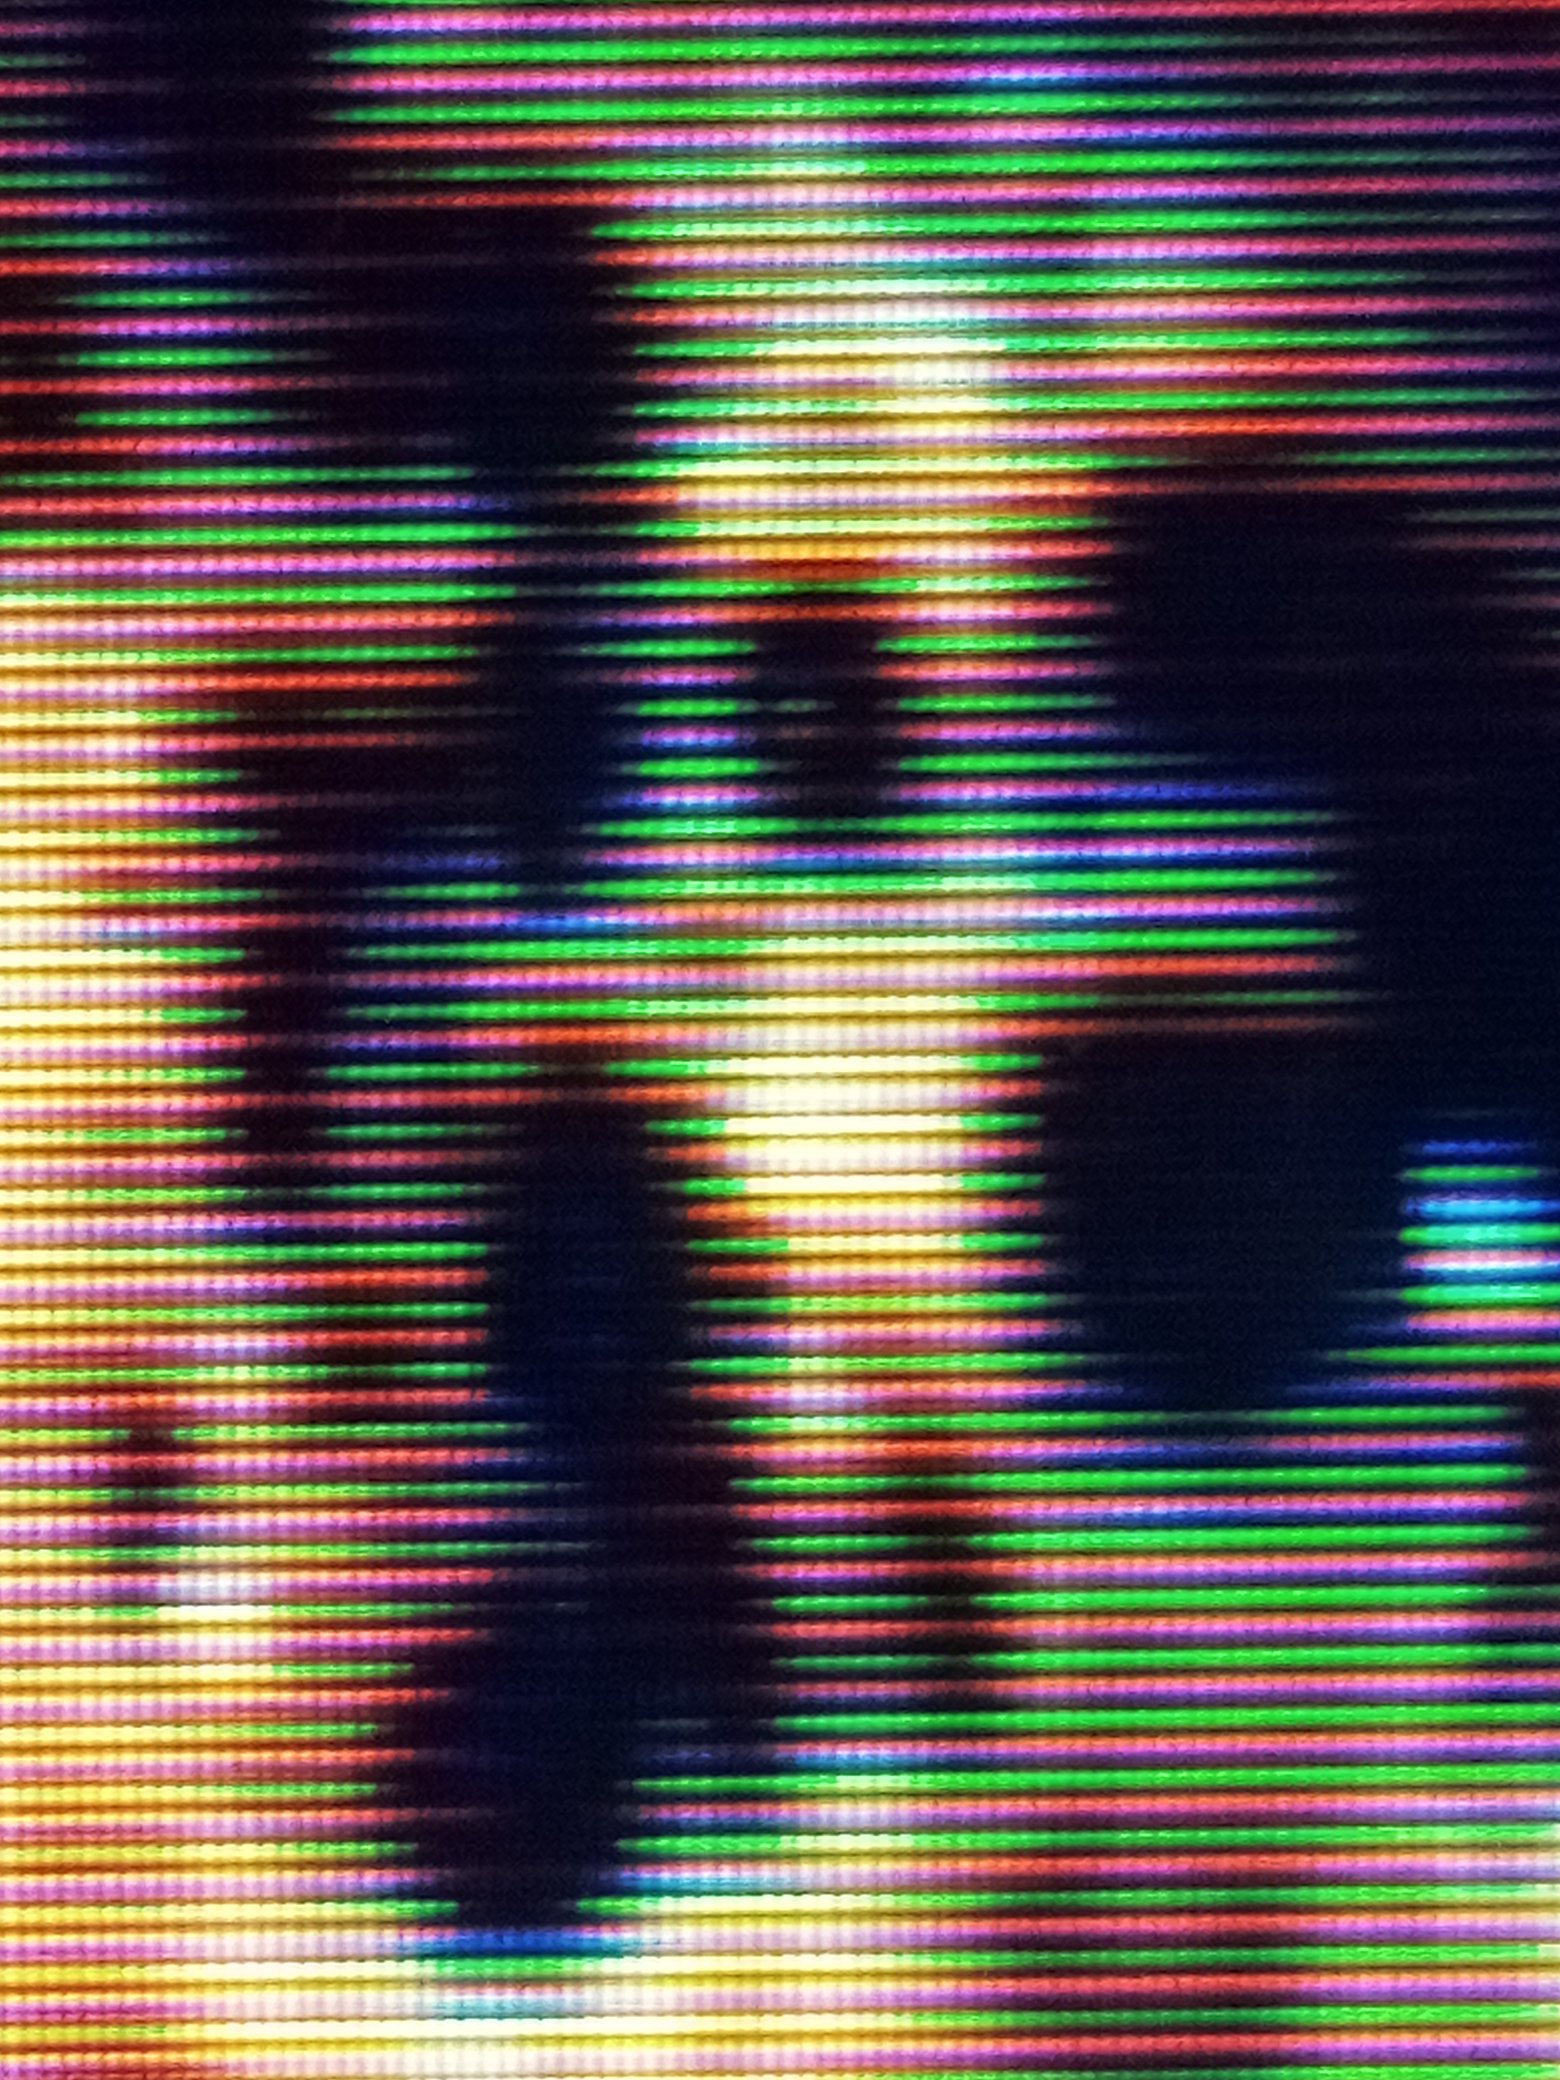
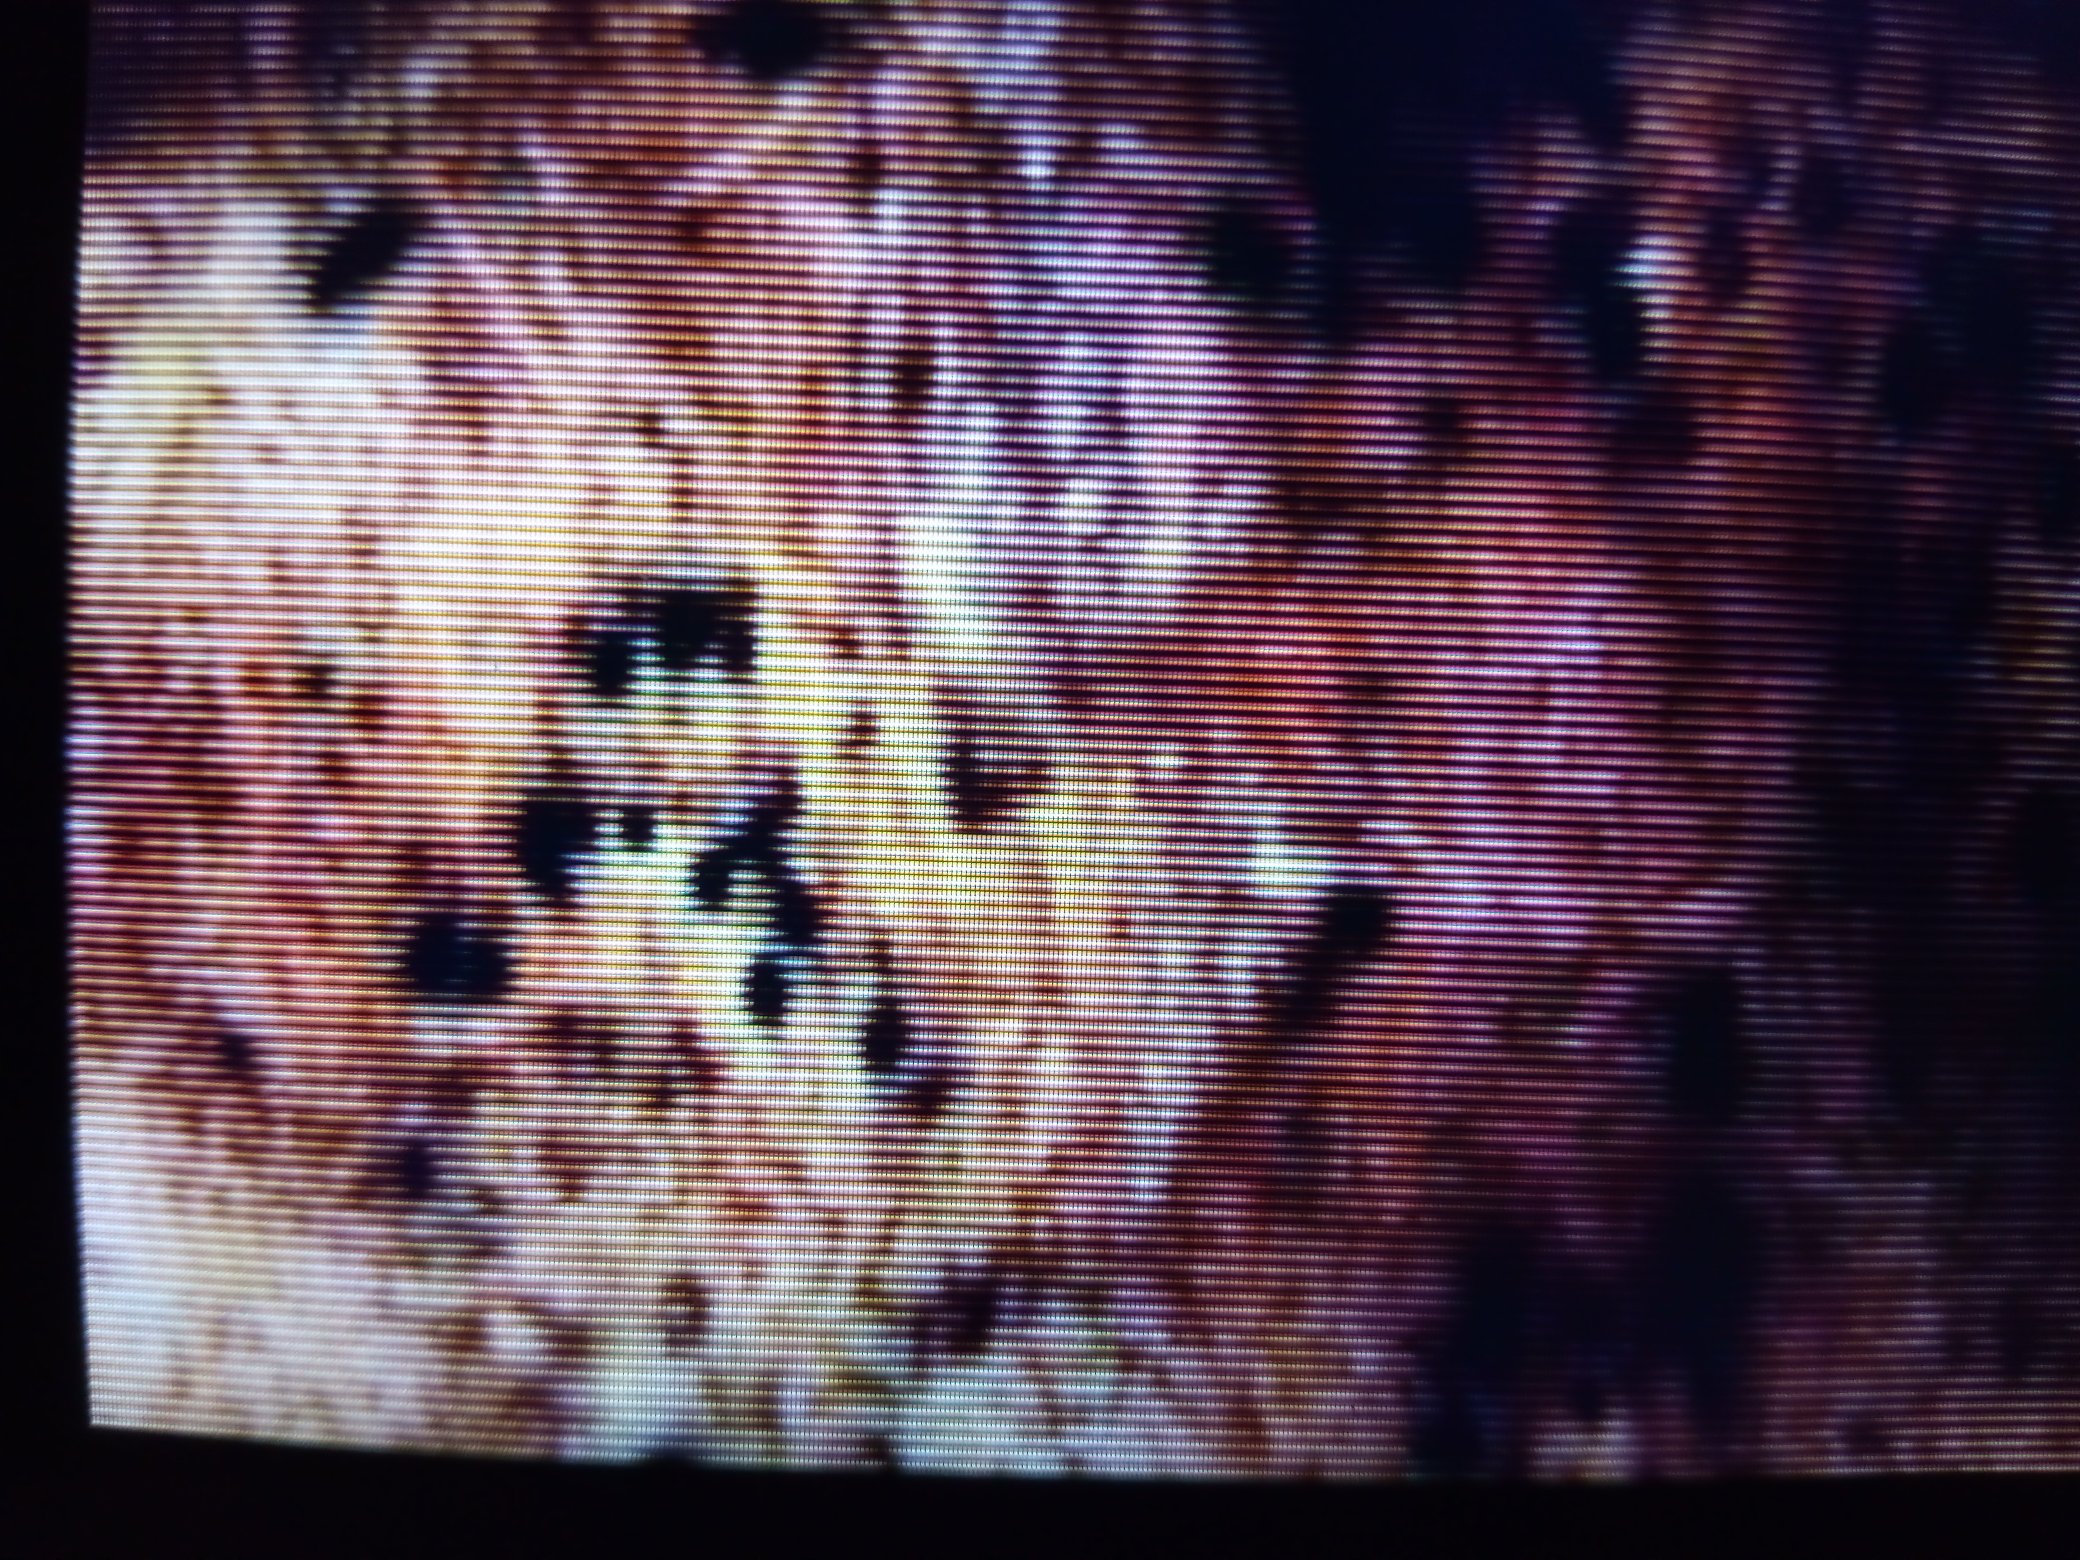
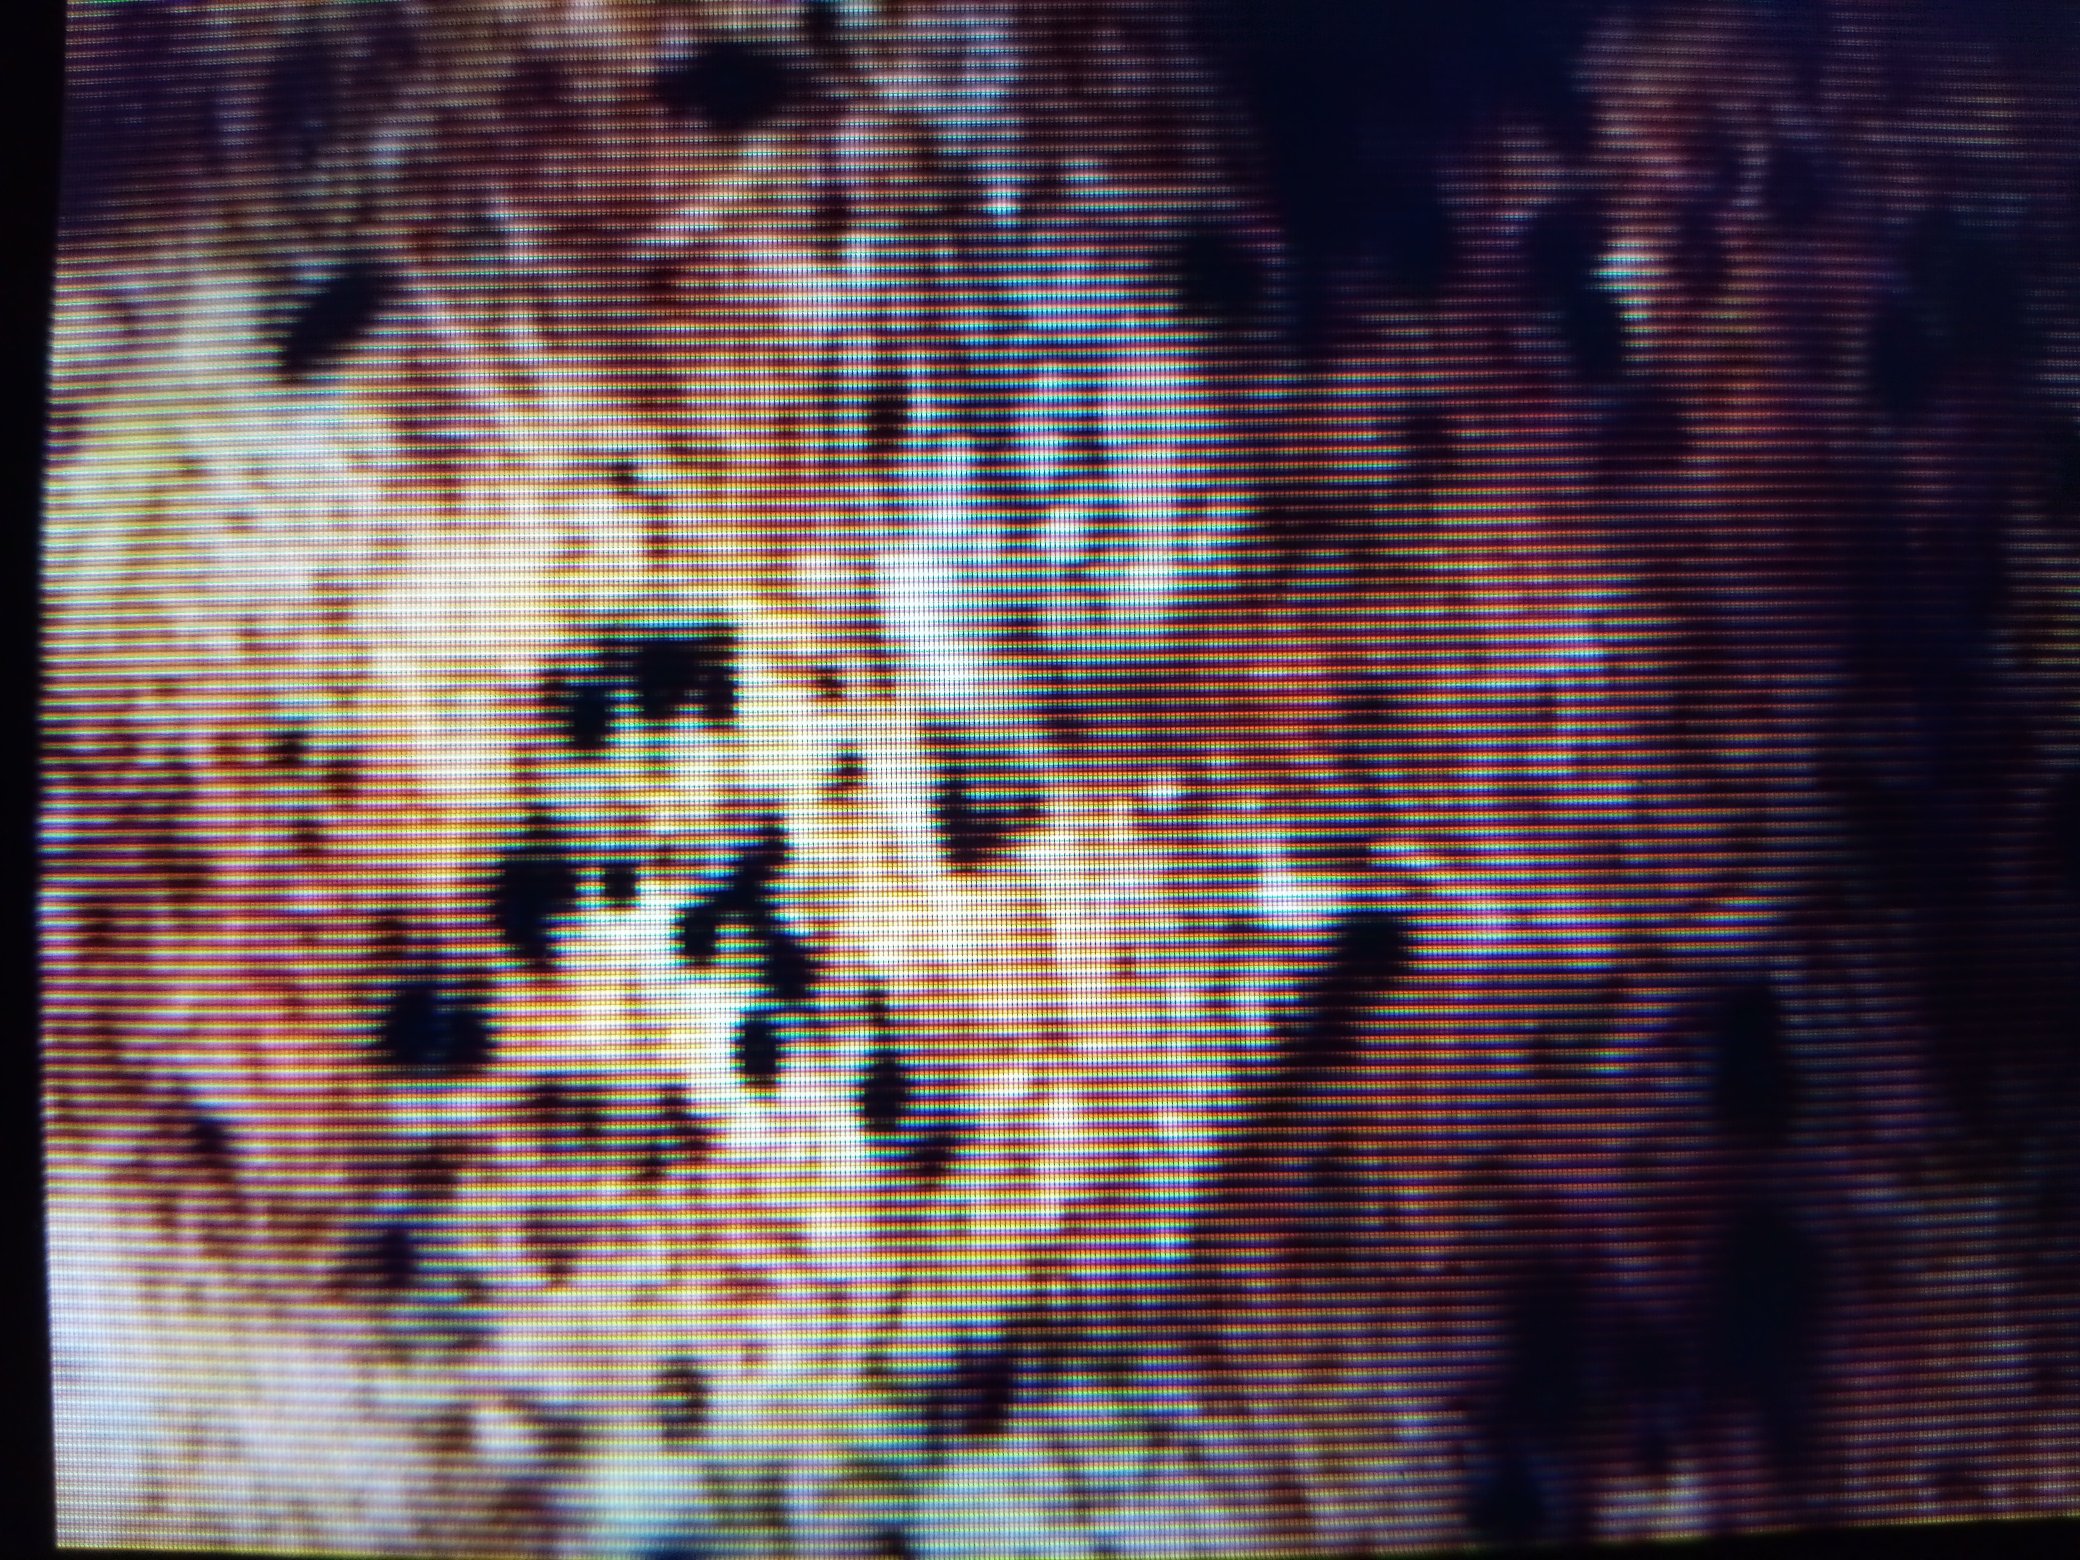
SPC: CRT shader on the Deck. This time not doing subpix render. Yet RGB vs BGR order matters still. One way it becomes possible to simulate even spaced aperture grill (removing scan fx), and the other more of the scan effect.
|
||||
|
||||
|
||||
|
||||
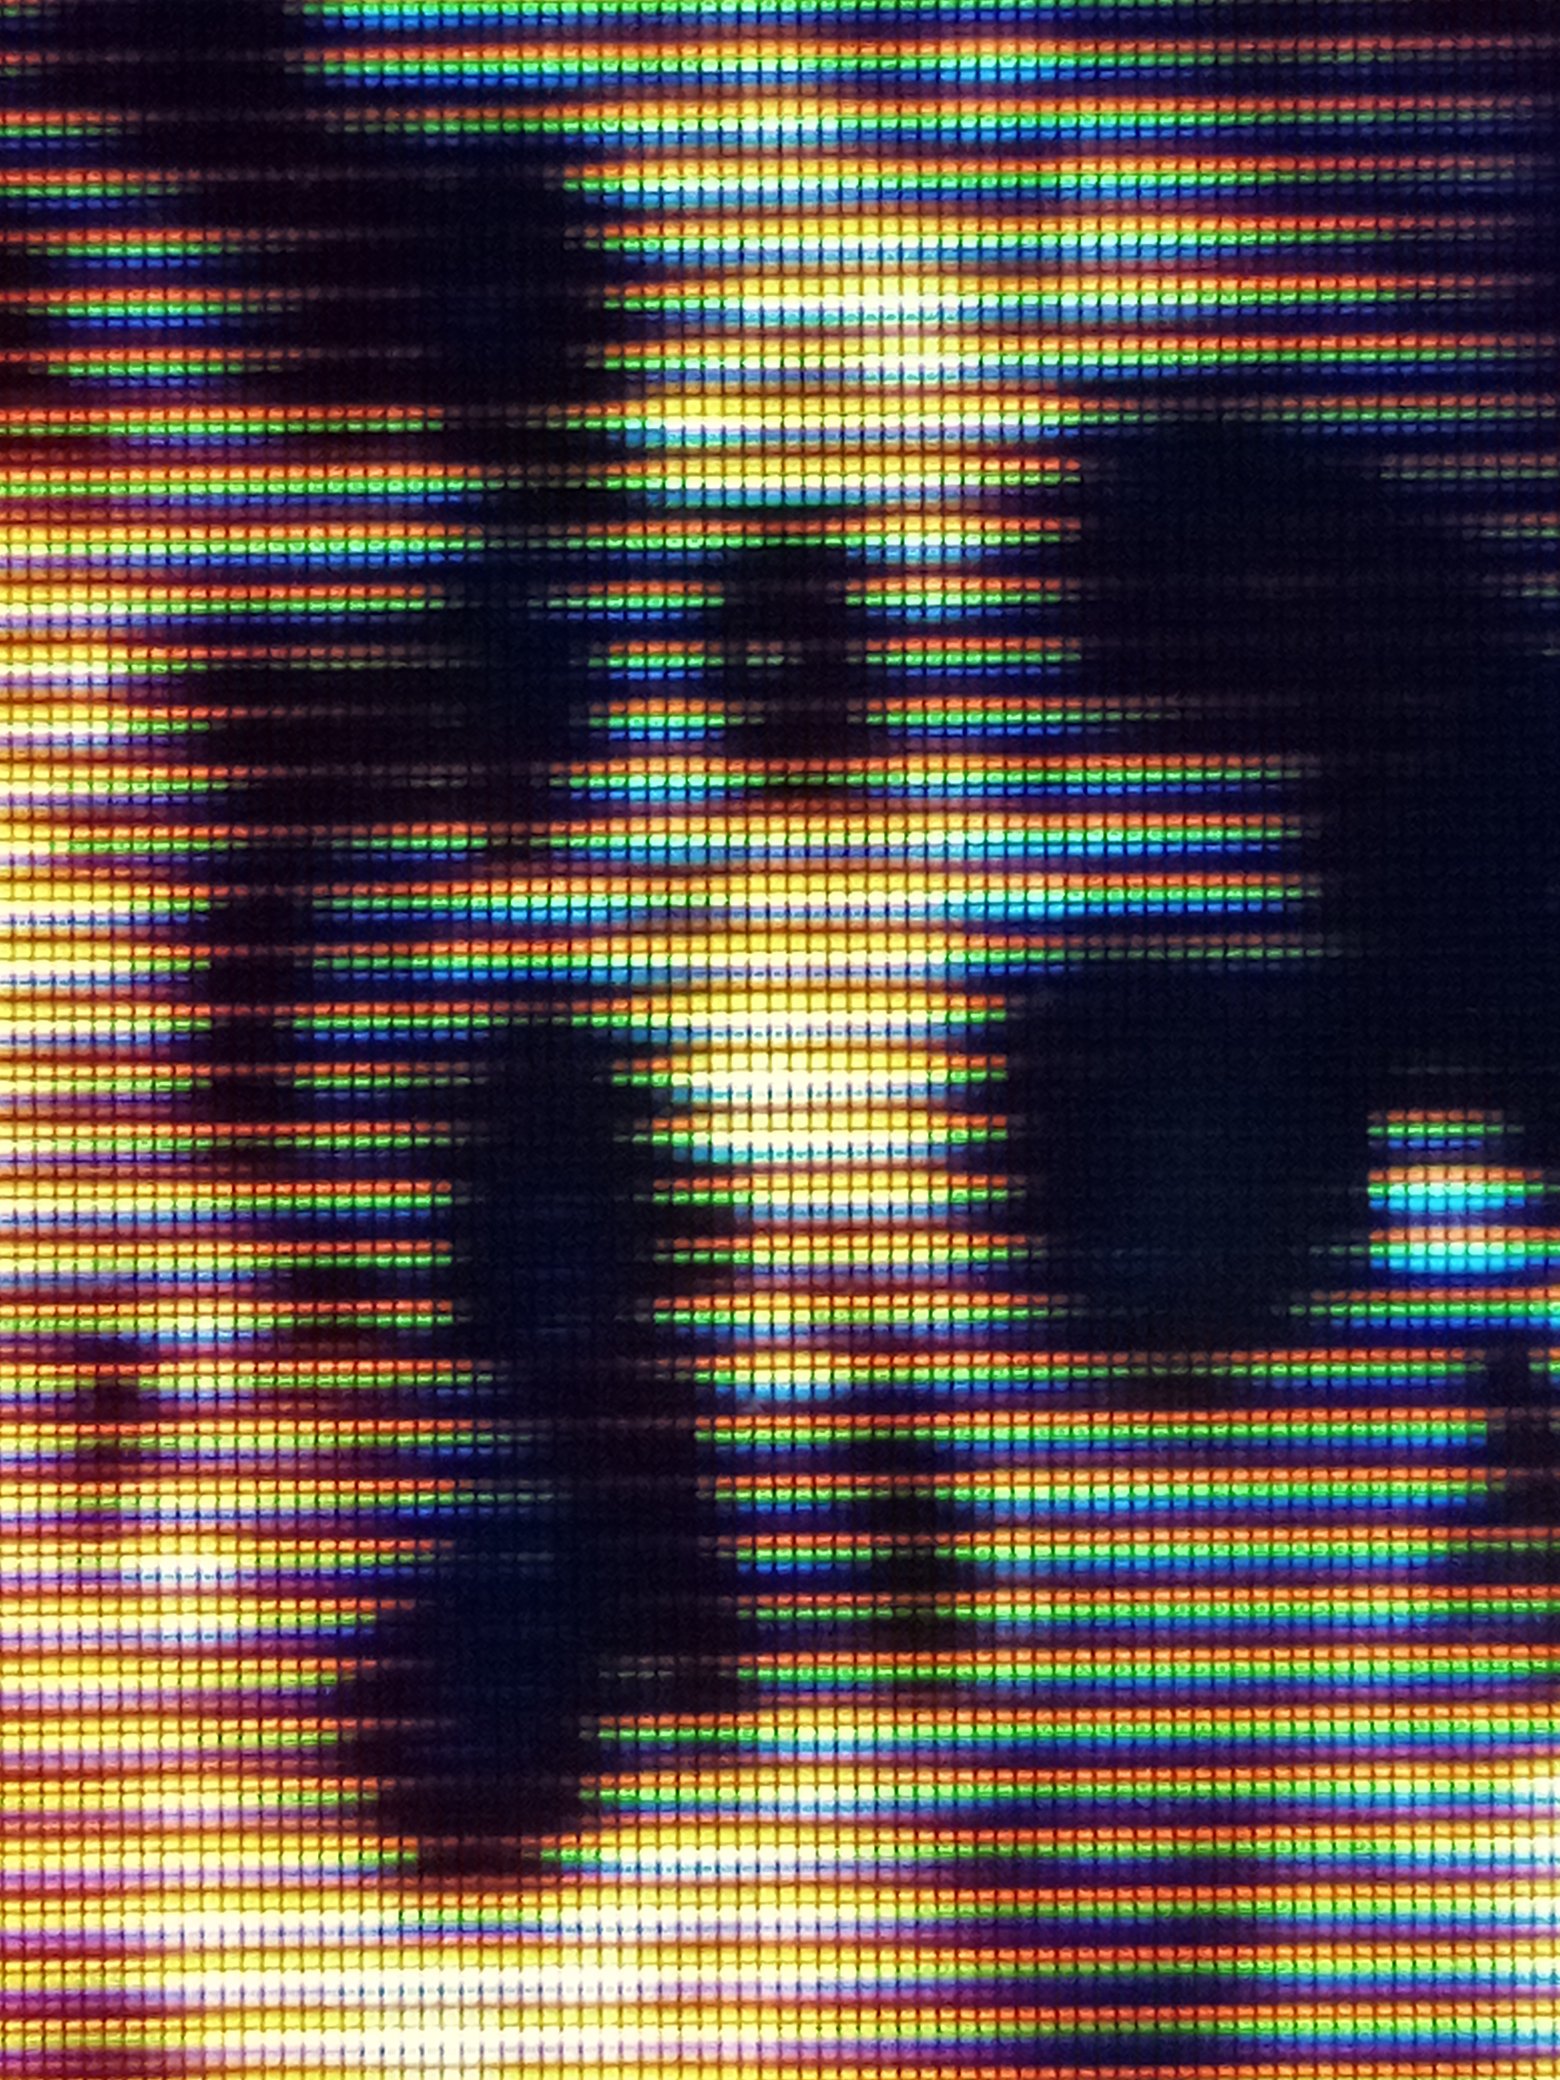
|
||||
|
||||
**2/**
|
||||
|
||||
Comparing all methods (grille, bad convergence scan, subpix scan)
|
||||
|
||||

|
||||
|
||||
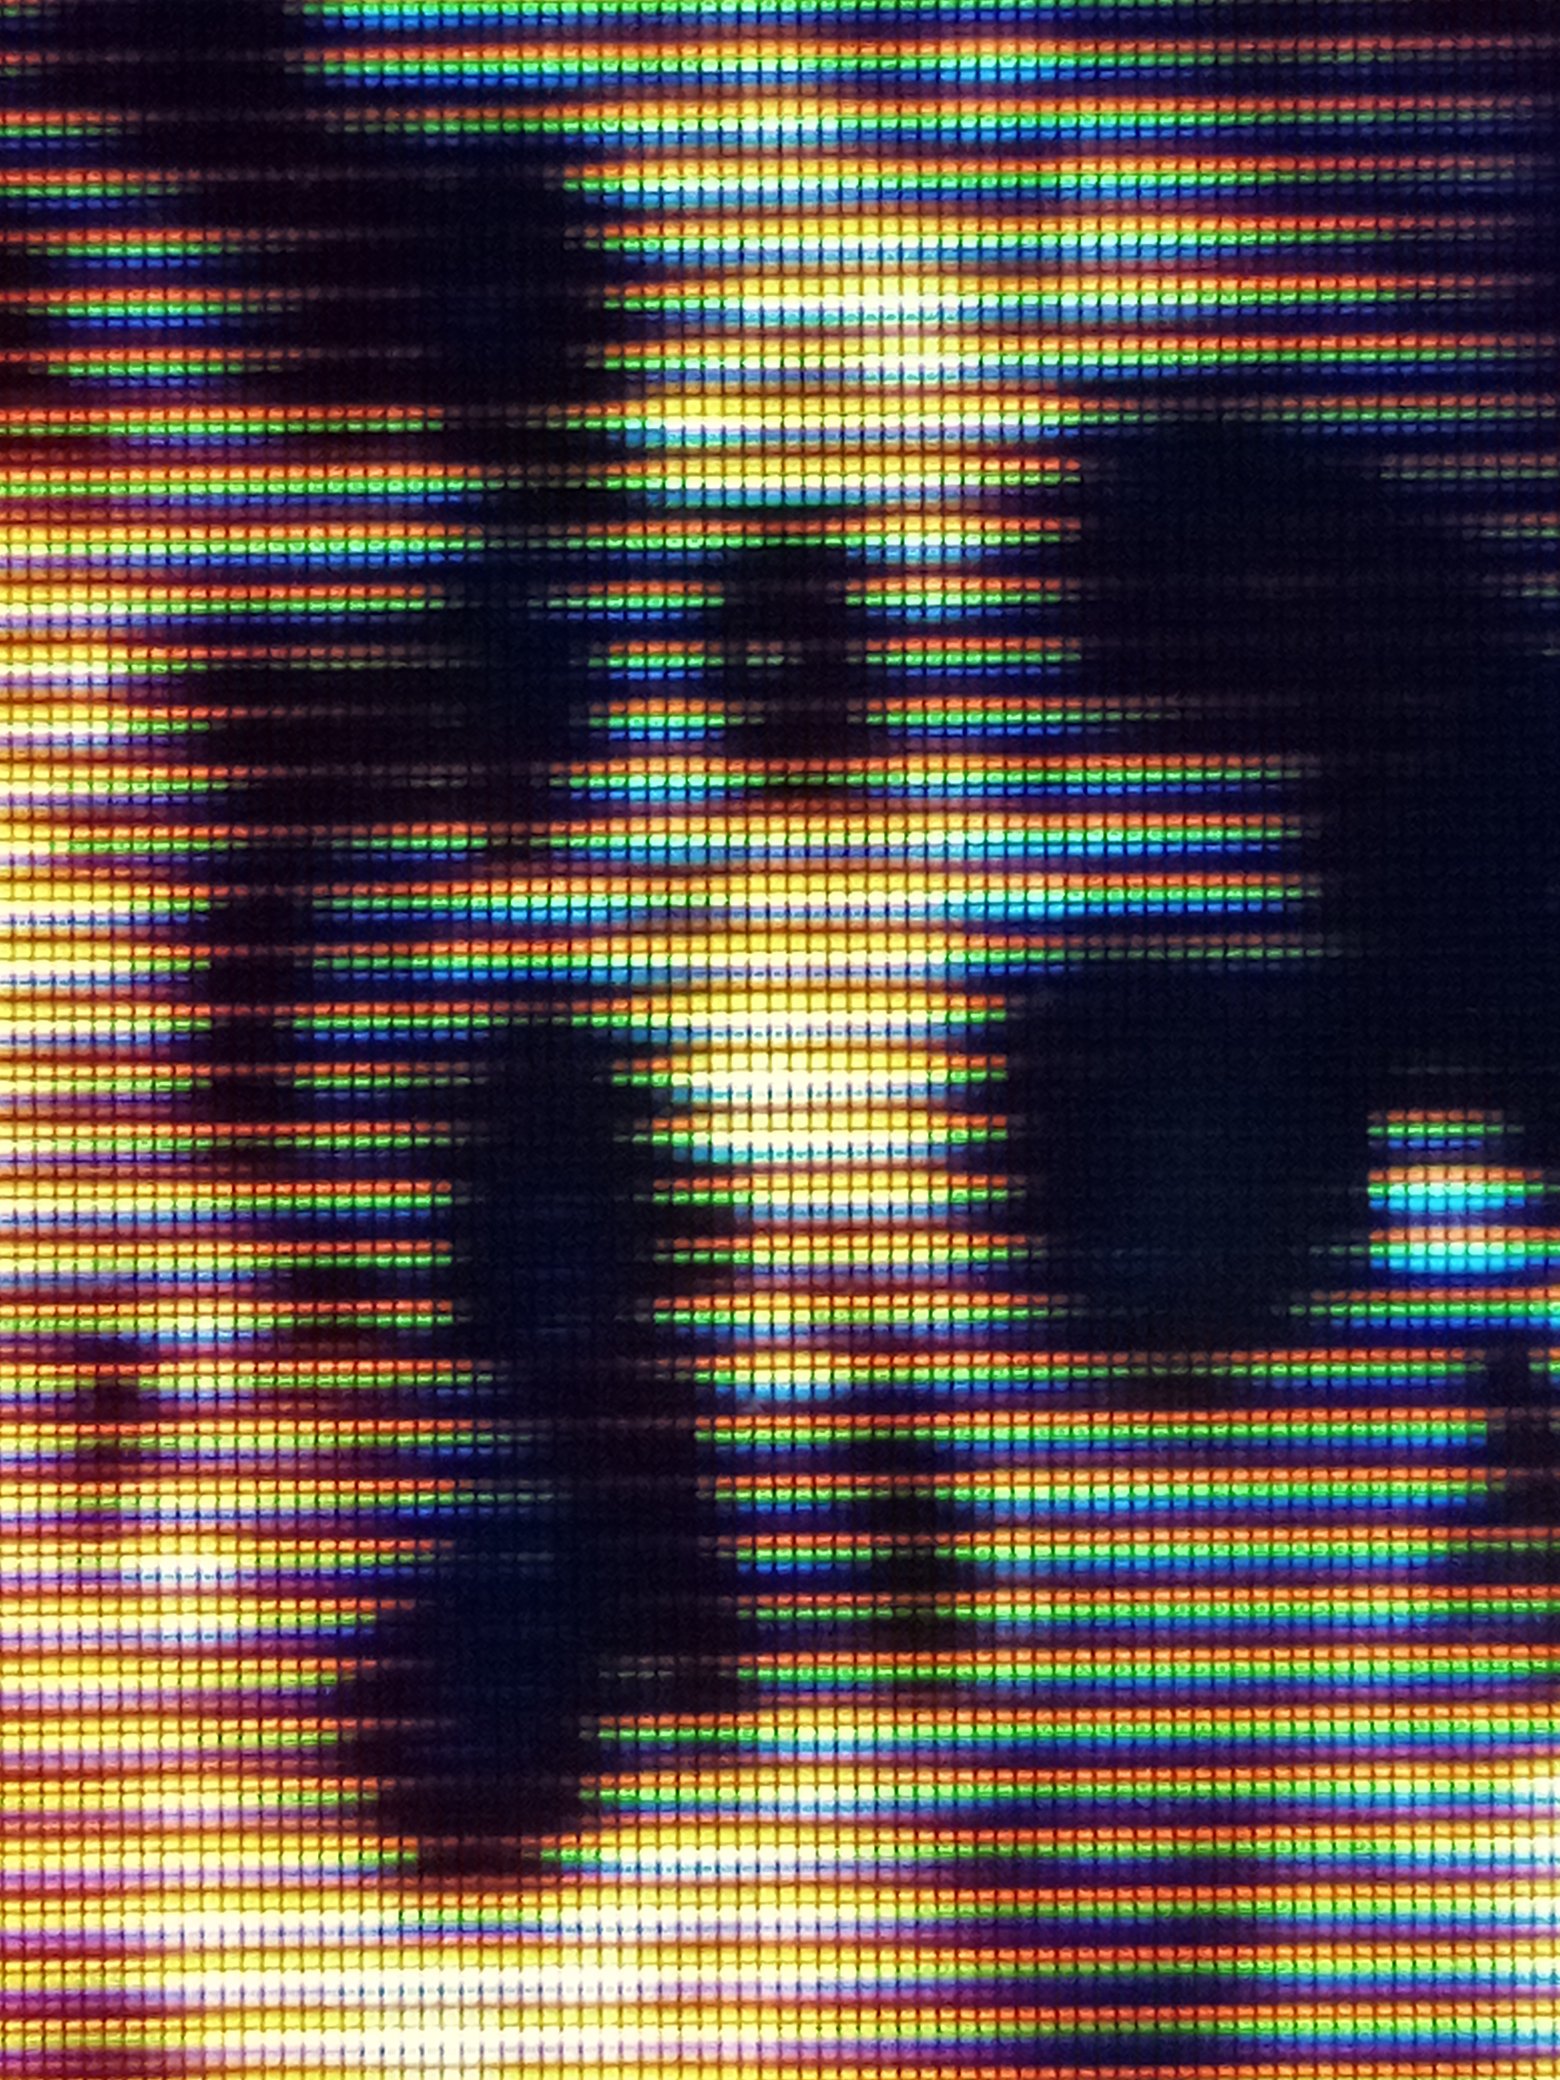
|
||||
|
||||
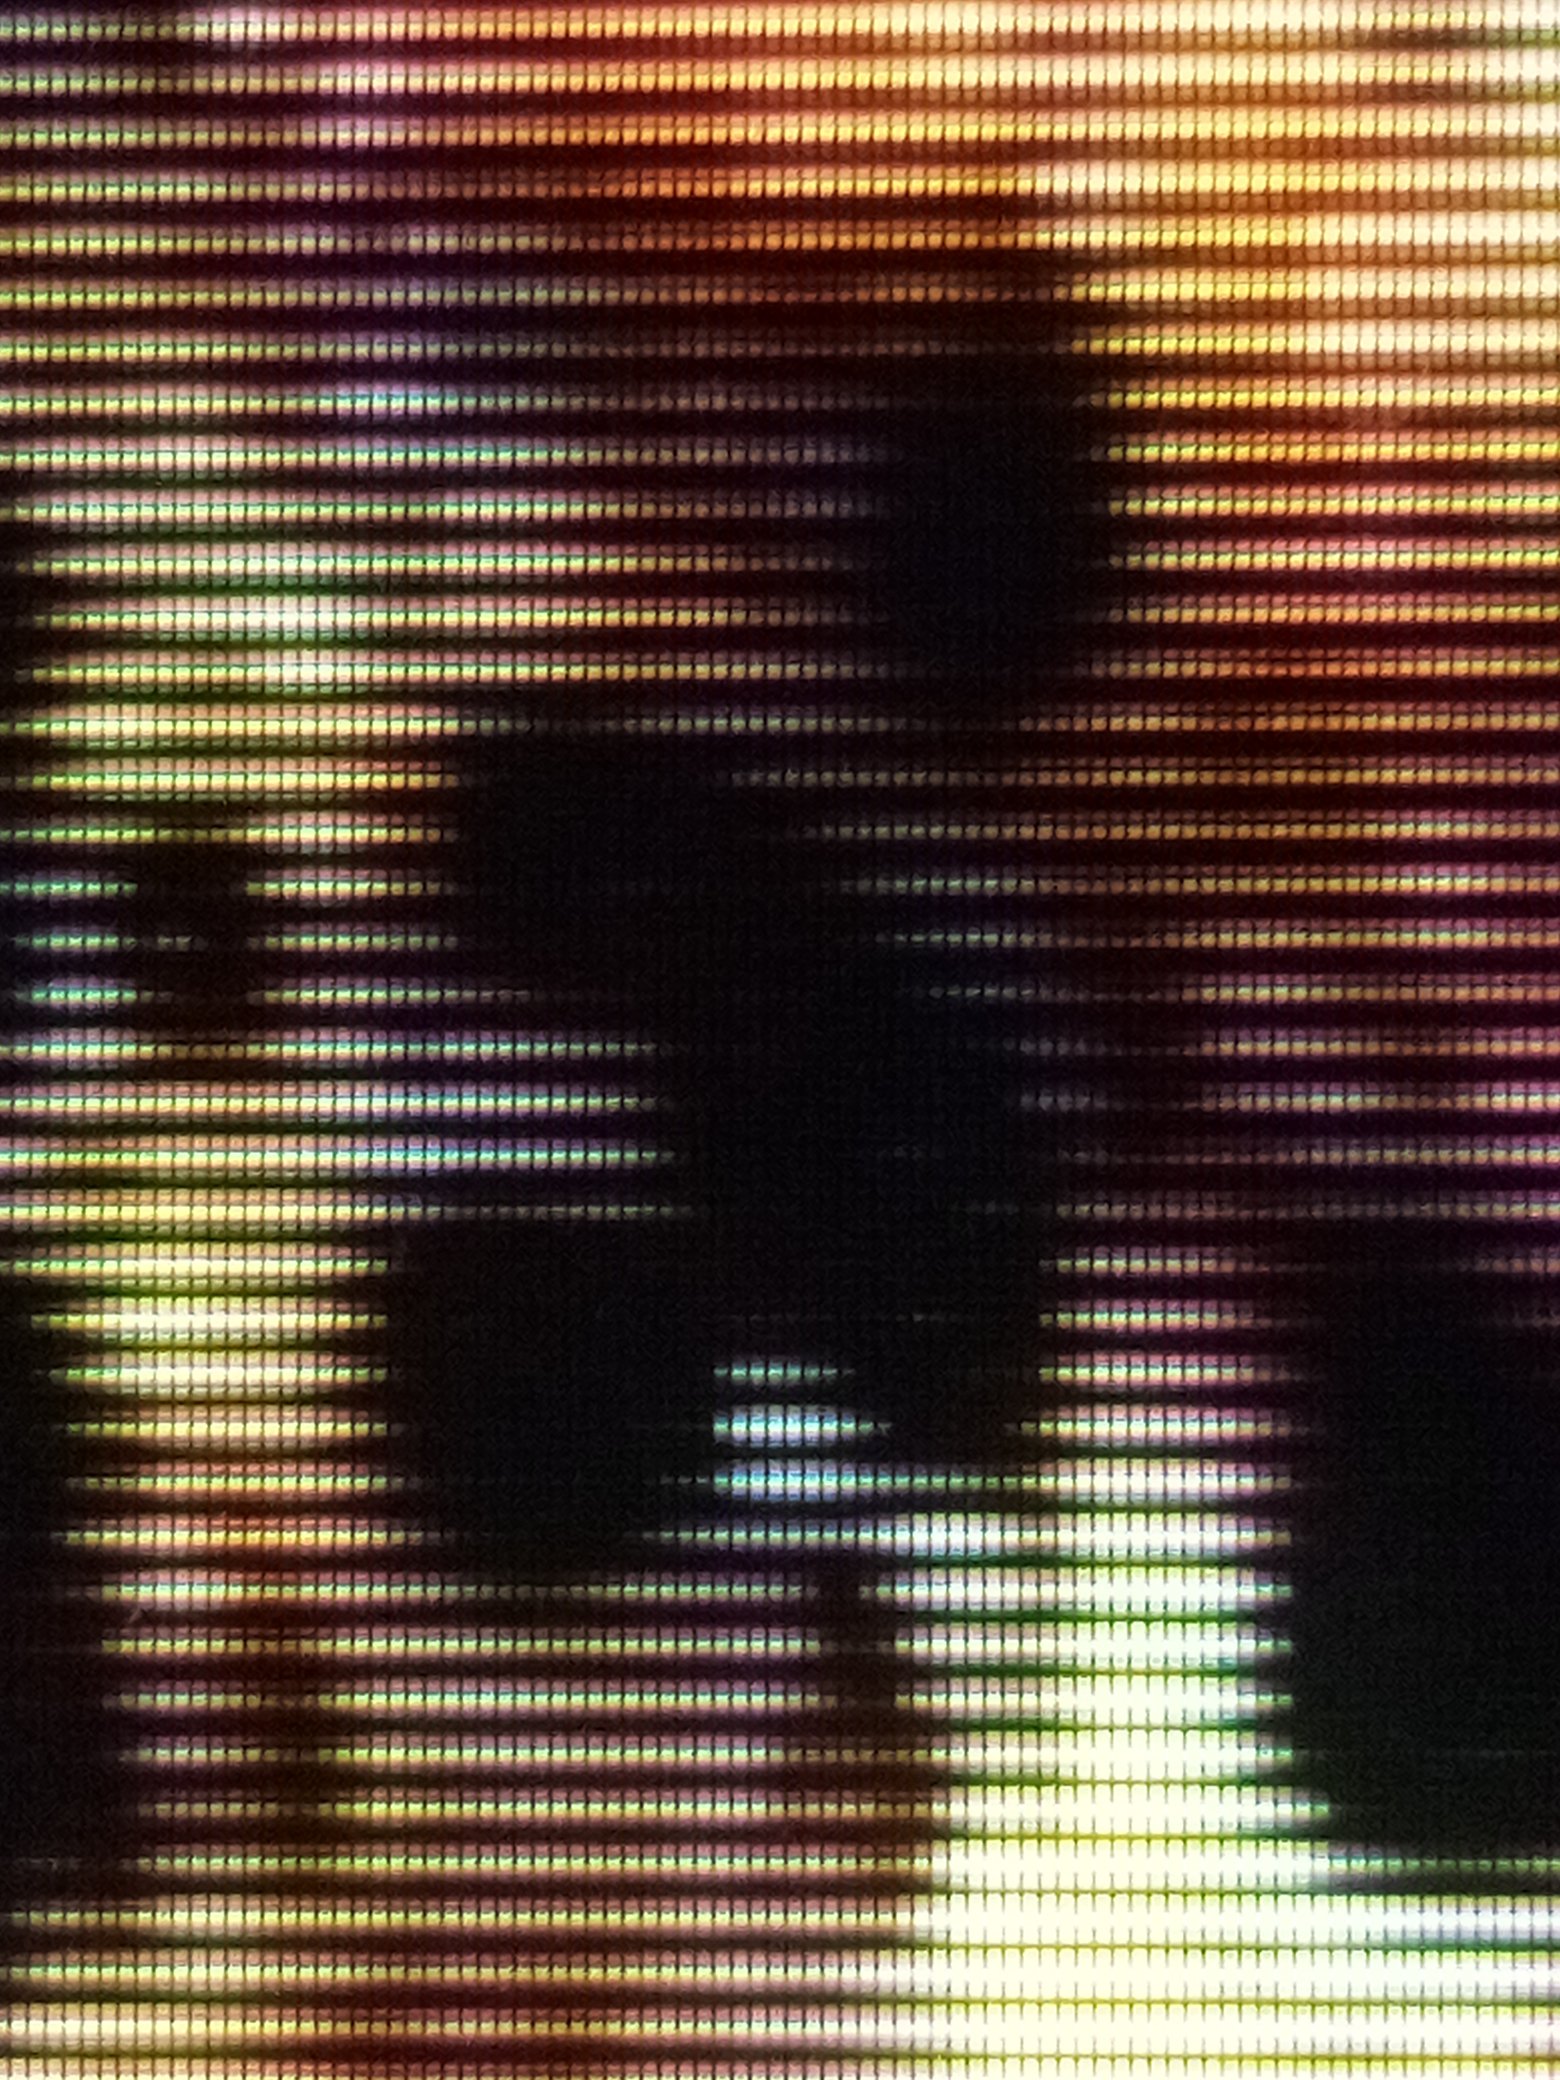
|
||||
|
||||
**3/**
|
||||
|
||||
The non-subpix scan has 1-pixel separation of RGB (intentional bad convergence) to help hide scaling. The subpix scan uses 1/3-pixel separation (less visible misaligned convergence). Pixel as in output pixel.
|
||||
|
||||
**4/**
|
||||
|
||||
The subpix version is definitely better. Because of the almost 3x doubling of scanline width detail, it just perceptually feels a lot cleaner and easier to reconstruct in the mind.
|
||||
|
||||
Media (not lifted): `1692565070583136348_F30y9HPWUAAbmmw_orig.jpg` `1692565070583136348_F30y9h3WAAETuui_orig.jpg`
|
||||
|
||||
|
||||
|
||||
@@ -1,21 +1,66 @@
|
||||
# twitter
|
||||
|
||||
Emit Threadwell archive notes from a `thread_data.json` dump. No fetch, no lift.
|
||||
Emit Threadwell archive notes from a `thread_data.json` dump. No fetch. Lift and CRT snapshot are still manual.
|
||||
|
||||
## One dump
|
||||
## Emit
|
||||
|
||||
```
|
||||
python C:\projects\Threadwell\scripts\twitter\emit_archive.py --input C:\projects\manual_slop\docs\twitter\2064858927829745887 --vault C:\projects\Threadwell --slug steamos-init --archived 2026-08-23
|
||||
```
|
||||
|
||||
`--input` is the dump directory. `--vault` is the Threadwell root. `--slug` overrides the directory slug. `--archived` is `YYYY-MM-DD` and defaults to today.
|
||||
`--tip <id>` climbs same-handle `reply_to` and uses that chain as `index.md`.
|
||||
|
||||
## All dumps
|
||||
`--all` skips a dump whose `post_id` already exists unless `--force`.
|
||||
|
||||
`--force` rewrites `media.json` to orig-only. Restore CRT/OCR rows with `media_merge.py`.
|
||||
|
||||
## Tip graph (no vault writes)
|
||||
|
||||
```
|
||||
python C:\projects\Threadwell\scripts\twitter\emit_archive.py --all C:\projects\manual_slop\docs\twitter --vault C:\projects\Threadwell --archived 2026-08-23
|
||||
python C:\projects\Threadwell\scripts\twitter\graph_dry_run.py --input C:\projects\manual_slop\docs\twitter\<id>
|
||||
```
|
||||
|
||||
Skips a dump whose `post_id` already exists in the vault unless `--force`. No fetch, no lift.
|
||||
## CRT (stock slang only)
|
||||
|
||||
The converter writes the spine and branch notes under `archive/threads/<handle>/<date-slug>/` and a working copy under `assets/threads/<handle>/<date-slug>/` (`thread_data.json`, `media.json`, `gaps.md`, and any local media). Media is not published.
|
||||
`crt_pass.py` nearest-scales, then runs **unpatched** `crt-lottes-multipass.slangp` / `crt-Cyclon.slangp` via `librashader-cli`. It does not edit shaders. ShaderGlass snapshot is still the look reference.
|
||||
|
||||
```
|
||||
python C:\projects\Threadwell\scripts\twitter\crt_pass.py --in ORIG.png --out CRT.png --preset cyclon --nn 3 --shader-scale 100% --dry-run
|
||||
```
|
||||
|
||||
`--nn 3` is Affinity 300%. `--shader-scale` is librashader `-d`. `--shaderglass` only launches the .sgp.
|
||||
|
||||
If the plate is wrong, snapshot ShaderGlass yourself and drop `*_crt.png` next to the orig, then `media_merge.py`.
|
||||
|
||||
## OCR
|
||||
|
||||
```
|
||||
python C:\projects\Threadwell\scripts\twitter\ocr_pass.py --in ORIG.png --media-json THREAD\media.json
|
||||
```
|
||||
|
||||
Prefers `umi-ocr` (`scoop install extras/umi-ocr`), then tesseract, then Windows.Media.Ocr. Writes `*_ocr.txt`. ShareX has no OCR CLI.
|
||||
|
||||
## Select CRT vs orig in the note
|
||||
|
||||
```
|
||||
python C:\projects\Threadwell\scripts\twitter\media_embed.py --thread ASSETS_THREAD --notes ARCHIVE_THREAD --media-id GBgHT_2WIAAKuNq --show crt
|
||||
python C:\projects\Threadwell\scripts\twitter\media_embed.py --thread ASSETS_THREAD --notes ARCHIVE_THREAD --media-id GBgHT_2WIAAKuNq --attach-ocr
|
||||
```
|
||||
|
||||
## Lift to catbox
|
||||
|
||||
```
|
||||
python C:\projects\Threadwell\scripts\twitter\lift_catbox.py --thread ASSETS_THREAD --notes ARCHIVE_THREAD --orig
|
||||
```
|
||||
|
||||
Reads `[catbox] userhash` from `secrets/credentials.toml`. Never prints it. Rewrites `Media (not lifted): \`file\`` to ``.
|
||||
|
||||
## Restore extra media.json rows
|
||||
|
||||
```
|
||||
python C:\projects\Threadwell\scripts\twitter\media_merge.py --thread ASSETS_THREAD
|
||||
```
|
||||
|
||||
## Frozen Onat
|
||||
|
||||
`do_not_refetch.txt` — do not overwrite those three dumps.
|
||||
@@ -0,0 +1,314 @@
|
||||
"""Apply a stock RetroArch slang preset to a still via librashader-cli.
|
||||
|
||||
Does not patch shaders. Does not invent PixelSize. Your ShaderGlass .sgp files
|
||||
are the look reference; this only runs the same .slangp with the listed params.
|
||||
|
||||
Manual look you are matching:
|
||||
1. Nearest-upscale the orig (Affinity zoom). 300% => 3x.
|
||||
2. Overlay ShaderGlass with the .sgp (Cyclon PixelSize 6, Lottes PixelSize 4).
|
||||
3. Snapshot, then crop.
|
||||
|
||||
This script can do step 1 (ffmpeg neighbor) and a stock slang render of the
|
||||
result. It cannot reproduce ShaderGlass window capture. If the plate is wrong,
|
||||
do it in ShaderGlass and drop the PNG next to the orig as *_crt.png.
|
||||
|
||||
Presets:
|
||||
lottes crt-lottes-multipass.slangp
|
||||
LOTTES_CODE_(LOTTES_MULTIPASS 2X) V2.sgp
|
||||
cyclon crt-Cyclon.slangp
|
||||
LOTTES_CRT_CODE_(CYCLON 6X).sgp
|
||||
|
||||
auto: cyclon if max(w,h) <= --auto-max (default 720), else lottes.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import shutil
|
||||
import subprocess
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
LOTTES_SGP = Path(
|
||||
r"C:\Users\Ed\Downloads\ShaderGlass-1.2.2-win-x64"
|
||||
r"\LOTTES_CODE_(LOTTES_MULTIPASS 2X) V2.sgp"
|
||||
)
|
||||
CYCLON_SGP = Path(
|
||||
r"C:\Users\Ed\Downloads\ShaderGlass-1.2.2-win-x64"
|
||||
r"\LOTTES_CRT_CODE_(CYCLON 6X).sgp"
|
||||
)
|
||||
SLANG_LOTTES = Path(
|
||||
r"C:\Users\Ed\scoop\apps\retroarch\1.22.2\shaders"
|
||||
r"\shaders_slang\crt\crt-lottes-multipass.slangp"
|
||||
)
|
||||
SLANG_CYCLON = Path(
|
||||
r"C:\Users\Ed\scoop\apps\retroarch\1.22.2\shaders"
|
||||
r"\shaders_slang\crt\crt-Cyclon.slangp"
|
||||
)
|
||||
CLI_DEFAULT = Path(r"C:\Users\Ed\scoop\apps\librashader\0.12.0\librashader-cli.exe")
|
||||
|
||||
# Knobs copied from the .sgp files. Not a substitute for PixelSize.
|
||||
LOTTES_PARAMS = (
|
||||
"hardScan=-19,hardPix=-7,warpX=0,warpY=0,maskDark=1.3,maskLight=1.3,"
|
||||
"shadowMask=4,brightBoost=1.15,bloomAmount=0,shape=1.9"
|
||||
)
|
||||
CYCLON_PARAMS = (
|
||||
"SCANLINE=0.2,INTERLACE=0,M_TYPE=0,SLOT=0,SLOTW=2,Maskl=0.55,Maskh=1,"
|
||||
"bzl=0,ambient=0,REFLECT=0,WARPX=0,WARPY=0,BR_DEP=0,BRIGHTNESS_=1.05,"
|
||||
"BLACK=0.01,vig=0"
|
||||
)
|
||||
|
||||
|
||||
def probe_size(path: Path) -> tuple[int, int]:
|
||||
raw = subprocess.check_output(
|
||||
[
|
||||
"ffprobe",
|
||||
"-v",
|
||||
"error",
|
||||
"-select_streams",
|
||||
"v:0",
|
||||
"-show_entries",
|
||||
"stream=width,height",
|
||||
"-of",
|
||||
"json",
|
||||
str(path),
|
||||
],
|
||||
text=True,
|
||||
)
|
||||
stream = json.loads(raw)["streams"][0]
|
||||
return int(stream["width"]), int(stream["height"])
|
||||
|
||||
|
||||
def pick_preset(width: int, height: int, name: str, auto_max: int) -> tuple[str, Path, Path, str]:
|
||||
if name == "auto":
|
||||
name = "cyclon" if max(width, height) <= auto_max else "lottes"
|
||||
if name == "lottes":
|
||||
return name, LOTTES_SGP, SLANG_LOTTES, LOTTES_PARAMS
|
||||
if name == "cyclon":
|
||||
return name, CYCLON_SGP, SLANG_CYCLON, CYCLON_PARAMS
|
||||
raise SystemExit(f"unknown preset {name}")
|
||||
|
||||
|
||||
def find_cli(explicit: Path | None) -> Path:
|
||||
if explicit is not None:
|
||||
if not explicit.is_file():
|
||||
raise SystemExit(f"missing --cli {explicit}")
|
||||
return explicit
|
||||
which = shutil.which("librashader-cli")
|
||||
if which:
|
||||
return Path(which)
|
||||
if CLI_DEFAULT.is_file():
|
||||
return CLI_DEFAULT
|
||||
raise SystemExit(
|
||||
"librashader-cli not on PATH. Install or pass --cli. "
|
||||
"Stock binary lives at "
|
||||
r"C:\Users\Ed\scoop\apps\librashader\0.12.0\librashader-cli.exe"
|
||||
)
|
||||
|
||||
|
||||
def parse_crop(spec: str) -> str | None:
|
||||
if spec in ("none", "", "off"):
|
||||
return None
|
||||
if spec == "auto":
|
||||
return "auto"
|
||||
parts = [int(p) for p in spec.replace(" ", "").split(",")]
|
||||
if len(parts) != 4:
|
||||
raise SystemExit("--crop wants auto, none, or L,T,R,B")
|
||||
left, top, right, bottom = parts
|
||||
return f"crop=iw-{left + right}:ih-{top + bottom}:{left}:{top}"
|
||||
|
||||
|
||||
def detect_crop(path: Path) -> str | None:
|
||||
proc = subprocess.run(
|
||||
[
|
||||
"ffmpeg",
|
||||
"-hide_banner",
|
||||
"-i",
|
||||
str(path),
|
||||
"-vf",
|
||||
"cropdetect=limit=24:round=2:reset=0",
|
||||
"-frames:v",
|
||||
"1",
|
||||
"-f",
|
||||
"null",
|
||||
"-",
|
||||
],
|
||||
capture_output=True,
|
||||
text=True,
|
||||
)
|
||||
crop = None
|
||||
for line in (proc.stderr or "").splitlines():
|
||||
if "crop=" in line:
|
||||
crop = line.rsplit("crop=", 1)[-1].strip()
|
||||
return f"crop={crop}" if crop else None
|
||||
|
||||
|
||||
def run_ffmpeg(src: Path, dest: Path, vf: str) -> None:
|
||||
dest.parent.mkdir(parents=True, exist_ok=True)
|
||||
subprocess.check_call(
|
||||
[
|
||||
"ffmpeg",
|
||||
"-y",
|
||||
"-hide_banner",
|
||||
"-loglevel",
|
||||
"error",
|
||||
"-i",
|
||||
str(src),
|
||||
"-vf",
|
||||
vf,
|
||||
"-frames:v",
|
||||
"1",
|
||||
"-update",
|
||||
"1",
|
||||
str(dest),
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
def run_librashader(
|
||||
cli: Path,
|
||||
slang: Path,
|
||||
src: Path,
|
||||
dest: Path,
|
||||
*,
|
||||
runtime: str,
|
||||
dimensions: str,
|
||||
params: str,
|
||||
) -> None:
|
||||
dest.parent.mkdir(parents=True, exist_ok=True)
|
||||
cmd = [
|
||||
str(cli),
|
||||
"render",
|
||||
"-r",
|
||||
runtime,
|
||||
"-d",
|
||||
dimensions,
|
||||
"--params",
|
||||
params,
|
||||
"-p",
|
||||
str(slang),
|
||||
"-i",
|
||||
str(src),
|
||||
"-o",
|
||||
str(dest),
|
||||
]
|
||||
print(" ".join(cmd))
|
||||
subprocess.check_call(cmd)
|
||||
|
||||
|
||||
def main(argv: list[str] | None = None) -> int:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--in", dest="src", type=Path, required=True)
|
||||
parser.add_argument("--out", dest="dest", type=Path, required=True)
|
||||
parser.add_argument("--preset", choices=("auto", "lottes", "cyclon"), default="auto")
|
||||
parser.add_argument(
|
||||
"--nn",
|
||||
type=int,
|
||||
default=1,
|
||||
help="nearest integer pre-scale (Affinity zoom). 1 = none, 3 = 300%%",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--shader-scale",
|
||||
default="100%",
|
||||
help="librashader -d on the (possibly nn-scaled) image. 100%%, 300%%, 600%%, or WIDTHxHEIGHT",
|
||||
)
|
||||
parser.add_argument("--runtime", default="d3d11")
|
||||
parser.add_argument("--auto-max", type=int, default=720)
|
||||
parser.add_argument("--crop", default="none", help="auto | none | L,T,R,B")
|
||||
parser.add_argument("--cli", type=Path, default=None)
|
||||
parser.add_argument("--dry-run", action="store_true")
|
||||
parser.add_argument(
|
||||
"--shaderglass",
|
||||
action="store_true",
|
||||
help="launch ShaderGlass with the matching .sgp (manual snapshot)",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--nn-only",
|
||||
action="store_true",
|
||||
help="only do the neighbor pre-scale; do not call librashader",
|
||||
)
|
||||
args = parser.parse_args(argv)
|
||||
|
||||
if not args.src.is_file():
|
||||
raise SystemExit(f"missing {args.src}")
|
||||
if args.nn < 1:
|
||||
raise SystemExit("--nn must be >= 1")
|
||||
|
||||
width, height = probe_size(args.src)
|
||||
name, sgp, slang, params = pick_preset(width, height, args.preset, args.auto_max)
|
||||
print(f"size {width}x{height} preset={name} nn={args.nn} shader-scale={args.shader_scale}")
|
||||
print(f"sgp {sgp}")
|
||||
print(f"slang {slang}")
|
||||
|
||||
work = args.src
|
||||
tmp_nn: Path | None = None
|
||||
if args.nn > 1:
|
||||
tmp_nn = args.dest.with_name(args.dest.stem + f"_nn{args.nn}.png")
|
||||
vf = f"scale=iw*{args.nn}:ih*{args.nn}:flags=neighbor,format=rgba"
|
||||
print("ffmpeg", "-i", work, "-vf", vf, tmp_nn)
|
||||
if not args.dry_run:
|
||||
run_ffmpeg(work, tmp_nn, vf)
|
||||
work = tmp_nn
|
||||
|
||||
if args.nn_only:
|
||||
if tmp_nn is None:
|
||||
raise SystemExit("--nn-only needs --nn > 1")
|
||||
if not args.dry_run:
|
||||
shutil.copy2(tmp_nn, args.dest)
|
||||
print(f"wrote {args.dest} (nn only)")
|
||||
return 0
|
||||
|
||||
cli = None if args.dry_run else find_cli(args.cli)
|
||||
if args.dry_run:
|
||||
print(
|
||||
"librashader-cli render",
|
||||
"-r",
|
||||
args.runtime,
|
||||
"-d",
|
||||
args.shader_scale,
|
||||
"--params",
|
||||
params,
|
||||
"-p",
|
||||
slang,
|
||||
"-i",
|
||||
work,
|
||||
"-o",
|
||||
args.dest,
|
||||
)
|
||||
else:
|
||||
assert cli is not None
|
||||
if not slang.is_file():
|
||||
raise SystemExit(f"missing slang {slang}")
|
||||
run_librashader(
|
||||
cli,
|
||||
slang,
|
||||
work,
|
||||
args.dest,
|
||||
runtime=args.runtime,
|
||||
dimensions=args.shader_scale,
|
||||
params=params,
|
||||
)
|
||||
|
||||
crop_spec = parse_crop(args.crop)
|
||||
if crop_spec == "auto" and not args.dry_run:
|
||||
crop_filter = detect_crop(args.dest)
|
||||
if crop_filter:
|
||||
cropped = args.dest.with_name(args.dest.stem + "_crop.png")
|
||||
run_ffmpeg(args.dest, cropped, crop_filter)
|
||||
shutil.move(str(cropped), str(args.dest))
|
||||
elif crop_spec and crop_spec != "auto" and not args.dry_run:
|
||||
cropped = args.dest.with_name(args.dest.stem + "_crop.png")
|
||||
run_ffmpeg(args.dest, cropped, crop_spec)
|
||||
shutil.move(str(cropped), str(args.dest))
|
||||
|
||||
print(f"wrote {args.dest}")
|
||||
if args.shaderglass:
|
||||
exe = shutil.which("shaderglass") or shutil.which("ShaderGlass")
|
||||
if not exe:
|
||||
raise SystemExit("shaderglass not on PATH")
|
||||
subprocess.Popen([exe, str(sgp)])
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,150 @@
|
||||
"""Upload curated stills to catbox and rewrite archive notes to HTTPS.
|
||||
|
||||
Reads userhash from vault secrets/credentials.toml [catbox]. Never prints it.
|
||||
|
||||
python lift_catbox.py --thread ASSETS_THREAD --notes ARCHIVE_THREAD --orig
|
||||
|
||||
--orig marks every on-disk orig row publish=true then uploads those.
|
||||
Default without --orig: only rows already publish=true.
|
||||
|
||||
After upload, any note token that is the local filename (backticked or
|
||||
bare) or a previous url for that row becomes .
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import re
|
||||
import subprocess
|
||||
import sys
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
API = "https://catbox.moe/user/api.php"
|
||||
CREDS = Path("secrets/credentials.toml")
|
||||
|
||||
|
||||
def load_userhash(vault: Path) -> str:
|
||||
path = vault / "secrets" / "credentials.toml"
|
||||
if not path.is_file():
|
||||
raise SystemExit(f"missing {path}")
|
||||
text = path.read_text(encoding="utf-8")
|
||||
try:
|
||||
data = tomllib.loads(text)
|
||||
h = str((data.get("catbox") or {}).get("userhash") or "").strip()
|
||||
except tomllib.TOMLDecodeError:
|
||||
h = ""
|
||||
in_catbox = False
|
||||
for raw in text.splitlines():
|
||||
line = raw.strip()
|
||||
if line.startswith("[") and line.endswith("]"):
|
||||
in_catbox = line[1:-1].strip().lower() == "catbox"
|
||||
continue
|
||||
if in_catbox and line.lower().startswith("userhash"):
|
||||
_, _, rest = line.partition("=")
|
||||
h = rest.strip().strip("\"'")
|
||||
break
|
||||
if not h:
|
||||
raise SystemExit("credentials.toml [catbox] userhash is empty")
|
||||
return h
|
||||
|
||||
|
||||
def upload(path: Path, userhash: str) -> str:
|
||||
cmd = [
|
||||
"curl.exe",
|
||||
"-sS",
|
||||
"-F",
|
||||
"reqtype=fileupload",
|
||||
"-F",
|
||||
f"userhash={userhash}",
|
||||
"-F",
|
||||
f"fileToUpload=@{path}",
|
||||
API,
|
||||
]
|
||||
raw = subprocess.check_output(cmd, text=True, stderr=subprocess.STDOUT)
|
||||
url = raw.strip()
|
||||
if not url.startswith("https://"):
|
||||
raise SystemExit(f"catbox refused {path.name}: {url[:200]}")
|
||||
return url
|
||||
|
||||
|
||||
def rewrite_notes(notes_dir: Path, old_tokens: list[str], url: str) -> int:
|
||||
embed = f""
|
||||
changed = 0
|
||||
for path in notes_dir.glob("*.md"):
|
||||
text = path.read_text(encoding="utf-8")
|
||||
new = text
|
||||
for token in old_tokens:
|
||||
if not token:
|
||||
continue
|
||||
new = new.replace(f"`{token}`", embed)
|
||||
new = new.replace(f"", embed)
|
||||
new = re.sub(r"^Media \(not lifted\):\s*", "", new, flags=re.M)
|
||||
while True:
|
||||
split = re.sub(
|
||||
r"(!\[[^\]]*\]\([^)]+\))\s+(!\[[^\]]*\]\([^)]+\))",
|
||||
r"\1\n\n\2",
|
||||
new,
|
||||
)
|
||||
if split == new:
|
||||
break
|
||||
new = split
|
||||
if new != text:
|
||||
path.write_text(new, encoding="utf-8", newline="\n")
|
||||
changed += 1
|
||||
print(f"rewrote {path.name}")
|
||||
return changed
|
||||
|
||||
|
||||
def main(argv: list[str] | None = None) -> int:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--vault", type=Path, default=Path(r"C:\projects\Threadwell"))
|
||||
parser.add_argument("--thread", type=Path, required=True)
|
||||
parser.add_argument("--notes", type=Path, required=True)
|
||||
parser.add_argument(
|
||||
"--orig",
|
||||
action="store_true",
|
||||
help="publish+upload every orig file that exists on disk",
|
||||
)
|
||||
parser.add_argument("--dry-run", action="store_true")
|
||||
args = parser.parse_args(argv)
|
||||
|
||||
media_path = args.thread / "media.json"
|
||||
data = json.loads(media_path.read_text(encoding="utf-8"))
|
||||
items = data.setdefault("items", [])
|
||||
if args.orig:
|
||||
for item in items:
|
||||
if item.get("role") == "orig":
|
||||
item["publish"] = True
|
||||
if "embed" not in item:
|
||||
item["embed"] = True
|
||||
|
||||
userhash = None if args.dry_run else load_userhash(args.vault)
|
||||
uploaded = 0
|
||||
for item in items:
|
||||
if not item.get("publish"):
|
||||
continue
|
||||
name = str(item.get("filename") or "")
|
||||
src = args.thread / name
|
||||
if not src.is_file():
|
||||
print(f"skip missing {name}")
|
||||
continue
|
||||
old = [name, str(item.get("url") or "")]
|
||||
if args.dry_run:
|
||||
print(f"would upload {name}")
|
||||
continue
|
||||
assert userhash is not None
|
||||
url = upload(src, userhash)
|
||||
item["url"] = url
|
||||
uploaded += 1
|
||||
print(f"uploaded {name} -> {url}")
|
||||
rewrite_notes(args.notes, old, url)
|
||||
|
||||
if not args.dry_run:
|
||||
media_path.write_text(json.dumps(data, indent=2) + "\n", encoding="utf-8")
|
||||
print(f"uploaded {uploaded}")
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,172 @@
|
||||
"""Select which still a note cites, and optionally attach OCR under it.
|
||||
|
||||
Notes currently say:
|
||||
|
||||
Media (not lifted): `1736…_GBgHT…_orig.png`
|
||||
|
||||
After lift they will say:
|
||||
|
||||

|
||||
|
||||
This script only rewrites those two shapes. It does not upload.
|
||||
|
||||
python media_embed.py --thread <assets-thread-dir> --notes <archive-thread-dir> --media-id GBgHT_2WIAAKuNq --show crt
|
||||
python media_embed.py --thread <assets-thread-dir> --notes <archive-thread-dir> --media-id GBgHT_2WIAAKuNq --attach-ocr
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
IMAGE_MD = re.compile(r"!\[([^\]]*)\]\(([^)]+)\)")
|
||||
LIFTED_LINE = re.compile(r"^Media \(not lifted\): (.+)$", re.M)
|
||||
|
||||
|
||||
def load_media(path: Path) -> dict:
|
||||
return json.loads(path.read_text(encoding="utf-8"))
|
||||
|
||||
|
||||
def save_media(path: Path, data: dict) -> None:
|
||||
path.write_text(json.dumps(data, indent=2) + "\n", encoding="utf-8")
|
||||
|
||||
|
||||
def group_items(items: list[dict]) -> dict[tuple[str, str], dict[str, dict]]:
|
||||
groups: dict[tuple[str, str], dict[str, dict]] = {}
|
||||
for item in items:
|
||||
key = (str(item.get("post_id") or ""), str(item.get("media_id") or ""))
|
||||
groups.setdefault(key, {})[str(item.get("role") or "")] = item
|
||||
return groups
|
||||
|
||||
|
||||
def set_embed(items: list[dict], media_id: str, show: str) -> None:
|
||||
found = False
|
||||
for item in items:
|
||||
if str(item.get("media_id") or "") != media_id:
|
||||
continue
|
||||
if item.get("role") in ("orig", "crt", "crt_outline"):
|
||||
item["embed"] = item.get("role") == show
|
||||
found = True
|
||||
if not found:
|
||||
raise SystemExit(f"no orig/crt row for media_id {media_id}")
|
||||
|
||||
|
||||
def token_for(item: dict) -> str:
|
||||
url = item.get("url")
|
||||
if url:
|
||||
return str(url)
|
||||
return str(item.get("filename") or "")
|
||||
|
||||
|
||||
def rewrite_notes(notes_dir: Path, old: str, new: str) -> int:
|
||||
if not old or old == new:
|
||||
return 0
|
||||
changed = 0
|
||||
for path in notes_dir.glob("*.md"):
|
||||
text = path.read_text(encoding="utf-8")
|
||||
if old not in text:
|
||||
continue
|
||||
path.write_text(text.replace(old, new), encoding="utf-8")
|
||||
changed += 1
|
||||
print(f"rewrote {path.name}")
|
||||
return changed
|
||||
|
||||
|
||||
def ocr_block(text: str) -> str:
|
||||
body = text.strip("\n")
|
||||
return (
|
||||
"<details>\n"
|
||||
"<summary>Text from still</summary>\n"
|
||||
"\n"
|
||||
"```\n"
|
||||
f"{body}\n"
|
||||
"```\n"
|
||||
"\n"
|
||||
"</details>"
|
||||
)
|
||||
|
||||
|
||||
def attach_ocr(notes_dir: Path, image_token: str, ocr_text: str) -> int:
|
||||
block = ocr_block(ocr_text)
|
||||
changed = 0
|
||||
for path in notes_dir.glob("*.md"):
|
||||
text = path.read_text(encoding="utf-8")
|
||||
if image_token not in text:
|
||||
continue
|
||||
if "<summary>Text from still</summary>" in text and image_token in text:
|
||||
print(f"ocr already near token in {path.name}")
|
||||
continue
|
||||
# After the line that cites the still.
|
||||
lines = text.splitlines(keepends=True)
|
||||
out: list[str] = []
|
||||
i = 0
|
||||
inserted = False
|
||||
while i < len(lines):
|
||||
out.append(lines[i])
|
||||
if image_token in lines[i] and not inserted:
|
||||
if not lines[i].endswith("\n"):
|
||||
out[-1] = lines[i] + "\n"
|
||||
out.append("\n")
|
||||
out.append(block + "\n")
|
||||
inserted = True
|
||||
i += 1
|
||||
if inserted:
|
||||
path.write_text("".join(out), encoding="utf-8")
|
||||
changed += 1
|
||||
print(f"attached ocr in {path.name}")
|
||||
return changed
|
||||
|
||||
|
||||
def main(argv: list[str] | None = None) -> int:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--thread", type=Path, required=True, help="assets/threads/.../ folder")
|
||||
parser.add_argument("--notes", type=Path, required=True, help="archive/threads/.../ folder")
|
||||
parser.add_argument("--media-id", required=True)
|
||||
parser.add_argument("--show", choices=("orig", "crt"), default=None)
|
||||
parser.add_argument("--attach-ocr", action="store_true")
|
||||
args = parser.parse_args(argv)
|
||||
|
||||
media_path = args.thread / "media.json"
|
||||
data = load_media(media_path)
|
||||
items = data["items"]
|
||||
groups = group_items(items)
|
||||
match = None
|
||||
pair = None
|
||||
for key, roles in groups.items():
|
||||
if key[1] == args.media_id:
|
||||
match = key
|
||||
pair = roles
|
||||
break
|
||||
if pair is None or match is None:
|
||||
raise SystemExit(f"media_id {args.media_id} not in {media_path}")
|
||||
|
||||
if args.show:
|
||||
if args.show not in pair:
|
||||
raise SystemExit(f"no role={args.show} for {args.media_id}")
|
||||
old_item = next((pair[r] for r in ("crt", "orig") if pair.get(r, {}).get("embed")), None)
|
||||
if old_item is None:
|
||||
old_item = pair.get("orig") or pair.get("crt")
|
||||
set_embed(items, args.media_id, args.show)
|
||||
save_media(media_path, data)
|
||||
new_item = pair[args.show]
|
||||
rewrite_notes(args.notes, token_for(old_item), token_for(new_item))
|
||||
print(f"embed {args.media_id} -> {args.show} ({token_for(new_item)})")
|
||||
|
||||
if args.attach_ocr:
|
||||
ocr = pair.get("ocr")
|
||||
if ocr is None:
|
||||
raise SystemExit(f"no role=ocr for {args.media_id}; run ocr_pass.py first")
|
||||
ocr_path = args.thread / str(ocr["filename"])
|
||||
if not ocr_path.is_file():
|
||||
raise SystemExit(f"missing {ocr_path}")
|
||||
shown = next((pair[r] for r in ("crt", "orig") if pair.get(r, {}).get("embed")), None)
|
||||
if shown is None:
|
||||
shown = pair.get("orig") or pair.get("crt")
|
||||
attach_ocr(args.notes, token_for(shown), ocr_path.read_text(encoding="utf-8"))
|
||||
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,83 @@
|
||||
"""Merge non-orig media.json rows back after emit --force.
|
||||
|
||||
emit collect_media rewrites media.json with orig only. CRT / OCR files stay
|
||||
on disk. Run this on the thread assets dir to restore those rows.
|
||||
|
||||
python media_merge.py --thread C:\\projects\\Threadwell\\assets\\threads\\HANDLE\\DATE-SLUG
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
from pathlib import Path
|
||||
|
||||
ROLE_SUFFIX = {
|
||||
"_crt.png": "crt",
|
||||
"_crt_outline.png": "crt_outline",
|
||||
"_denoise.png": "denoise",
|
||||
"_ocr.txt": "ocr",
|
||||
}
|
||||
|
||||
|
||||
def role_of(name: str) -> str | None:
|
||||
for suffix, role in ROLE_SUFFIX.items():
|
||||
if name.endswith(suffix):
|
||||
return role
|
||||
return None
|
||||
|
||||
|
||||
def parse_ids(name: str) -> tuple[str, str]:
|
||||
stem = name
|
||||
for suffix in ROLE_SUFFIX:
|
||||
if stem.endswith(suffix):
|
||||
stem = stem[: -len(suffix)]
|
||||
break
|
||||
if stem.endswith("_orig"):
|
||||
stem = stem[: -len("_orig")]
|
||||
parts = stem.split("_", 1)
|
||||
if len(parts) != 2:
|
||||
return "", stem
|
||||
return parts[0], parts[1]
|
||||
|
||||
|
||||
def main(argv: list[str] | None = None) -> int:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--thread", type=Path, required=True)
|
||||
args = parser.parse_args(argv)
|
||||
media_path = args.thread / "media.json"
|
||||
data = json.loads(media_path.read_text(encoding="utf-8"))
|
||||
items = list(data.get("items") or [])
|
||||
have = {(i.get("filename"), i.get("role")) for i in items}
|
||||
added = 0
|
||||
for path in sorted(args.thread.iterdir()):
|
||||
role = role_of(path.name)
|
||||
if role is None:
|
||||
continue
|
||||
if (path.name, role) in have:
|
||||
continue
|
||||
post_id, media_id = parse_ids(path.name)
|
||||
handle = ""
|
||||
for item in items:
|
||||
if item.get("media_id") == media_id:
|
||||
handle = str(item.get("handle") or "")
|
||||
break
|
||||
items.append({
|
||||
"post_id": post_id,
|
||||
"media_id": media_id,
|
||||
"handle": handle,
|
||||
"role": role,
|
||||
"filename": path.name,
|
||||
"publish": False,
|
||||
"url": None,
|
||||
"embed": False,
|
||||
})
|
||||
added += 1
|
||||
print(f"restore {path.name} role={role}")
|
||||
data["items"] = items
|
||||
media_path.write_text(json.dumps(data, indent=2) + "\n", encoding="utf-8")
|
||||
print(f"added {added} -> {media_path}")
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,215 @@
|
||||
"""OCR a still. Prefer Umi-OCR HTTP, then tesseract, then Windows.Media.Ocr.
|
||||
|
||||
Writes UTF-8 text. Optional: add a role=ocr row to media.json.
|
||||
|
||||
Umi-OCR must be running (HTTP :1224). Start Umi-OCR.exe once. Then:
|
||||
|
||||
python ocr_pass.py --in still.png --engine umi
|
||||
|
||||
Uses tbpu.parser=single_code (keep indent) and English. ShareX has no OCR CLI.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import base64
|
||||
import json
|
||||
import shutil
|
||||
import subprocess
|
||||
import sys
|
||||
import urllib.error
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
|
||||
UMI_URL = "http://127.0.0.1:1224/api/ocr"
|
||||
|
||||
|
||||
def find_umi() -> str | None:
|
||||
return shutil.which("umi-ocr") or shutil.which("Umi-OCR")
|
||||
|
||||
|
||||
def find_tesseract() -> str | None:
|
||||
return shutil.which("tesseract")
|
||||
|
||||
|
||||
def umi_http_up() -> bool:
|
||||
try:
|
||||
urllib.request.urlopen("http://127.0.0.1:1224/api/ocr/get_options", timeout=2)
|
||||
return True
|
||||
except (urllib.error.URLError, TimeoutError, OSError):
|
||||
return False
|
||||
|
||||
|
||||
def run_umi(src: Path, dest: Path) -> None:
|
||||
dest.parent.mkdir(parents=True, exist_ok=True)
|
||||
if not umi_http_up():
|
||||
exe = find_umi()
|
||||
if exe:
|
||||
subprocess.Popen([exe])
|
||||
raise SystemExit(
|
||||
"Umi-OCR HTTP not on 127.0.0.1:1224. Start Umi-OCR.exe and retry."
|
||||
)
|
||||
payload = {
|
||||
"base64": base64.b64encode(src.read_bytes()).decode("ascii"),
|
||||
"options": {
|
||||
"ocr.language": "English",
|
||||
"tbpu.parser": "single_code",
|
||||
"ocr.maxSideLen": 999999,
|
||||
"data.format": "text",
|
||||
},
|
||||
}
|
||||
req = urllib.request.Request(
|
||||
UMI_URL,
|
||||
data=json.dumps(payload).encode("utf-8"),
|
||||
headers={"Content-Type": "application/json"},
|
||||
)
|
||||
print(f"umi-http {src.name}")
|
||||
raw = urllib.request.urlopen(req, timeout=180).read()
|
||||
res = json.loads(raw.decode("utf-8"))
|
||||
code = res.get("code")
|
||||
data = res.get("data")
|
||||
if code == 100 and isinstance(data, str):
|
||||
text = data
|
||||
elif code == 101:
|
||||
text = ""
|
||||
elif isinstance(data, list):
|
||||
text = "".join(
|
||||
str(block.get("text", "")) + str(block.get("end", "")) for block in data
|
||||
)
|
||||
else:
|
||||
raise SystemExit(f"umi-ocr failed code={code} data={data!r}")
|
||||
dest.write_text(text.replace("\r\n", "\n"), encoding="utf-8")
|
||||
|
||||
|
||||
def run_tesseract(src: Path, dest: Path) -> None:
|
||||
exe = find_tesseract()
|
||||
if not exe:
|
||||
raise SystemExit("tesseract not on PATH. scoop install tesseract")
|
||||
dest.parent.mkdir(parents=True, exist_ok=True)
|
||||
out_base = dest.with_suffix("")
|
||||
cmd = [exe, str(src), str(out_base), "-l", "eng"]
|
||||
print(" ".join(cmd))
|
||||
subprocess.check_call(cmd)
|
||||
txt = out_base.with_suffix(".txt")
|
||||
if txt != dest:
|
||||
dest.write_text(txt.read_text(encoding="utf-8", errors="replace"), encoding="utf-8")
|
||||
|
||||
|
||||
def run_windows_ocr(src: Path, dest: Path) -> None:
|
||||
ps = r"""
|
||||
$ErrorActionPreference = 'Stop'
|
||||
Add-Type -AssemblyName System.Runtime.WindowsRuntime
|
||||
$null = [Windows.Storage.StorageFile, Windows.Storage, ContentType = WindowsRuntime]
|
||||
$null = [Windows.Graphics.Imaging.BitmapDecoder, Windows.Graphics.Imaging, ContentType = WindowsRuntime]
|
||||
$null = [Windows.Media.Ocr.OcrEngine, Windows.Media.Ocr, ContentType = WindowsRuntime]
|
||||
function Await($op) {
|
||||
$asTask = [System.WindowsRuntimeSystemExtensions].GetMethods() | Where-Object {
|
||||
$_.Name -eq 'AsTask' -and $_.GetParameters().Count -eq 1
|
||||
} | Select-Object -First 1
|
||||
$task = $asTask.MakeGenericMethod($op.GetType().GenericTypeArguments[0]).Invoke($null, @($op))
|
||||
$task.Wait()
|
||||
$task.Result
|
||||
}
|
||||
$src = $args[0]
|
||||
$dest = $args[1]
|
||||
$file = Await ([Windows.Storage.StorageFile]::GetFileFromPathAsync($src))
|
||||
$stream = Await ($file.OpenAsync([Windows.Storage.FileAccessMode]::Read))
|
||||
$decoder = Await ([Windows.Graphics.Imaging.BitmapDecoder]::CreateAsync($stream))
|
||||
$bitmap = Await ($decoder.GetSoftwareBitmapAsync())
|
||||
$engine = [Windows.Media.Ocr.OcrEngine]::TryCreateFromUserProfileLanguages()
|
||||
if ($null -eq $engine) { throw 'Windows OCR engine unavailable' }
|
||||
$result = Await ($engine.RecognizeAsync($bitmap))
|
||||
[System.IO.File]::WriteAllText($dest, $result.Text, [System.Text.UTF8Encoding]::new($false))
|
||||
"""
|
||||
dest.parent.mkdir(parents=True, exist_ok=True)
|
||||
cmd = [
|
||||
"powershell",
|
||||
"-NoProfile",
|
||||
"-Command",
|
||||
ps,
|
||||
str(src.resolve()),
|
||||
str(dest.resolve()),
|
||||
]
|
||||
print("windows.media.ocr", src.name)
|
||||
subprocess.check_call(cmd)
|
||||
|
||||
|
||||
def append_media_row(media_json: Path, src: Path, dest: Path) -> None:
|
||||
data = json.loads(media_json.read_text(encoding="utf-8"))
|
||||
items = data.setdefault("items", [])
|
||||
stem = src.name
|
||||
post_id = ""
|
||||
media_id = ""
|
||||
handle = ""
|
||||
for item in items:
|
||||
if item.get("filename") == src.name or item.get("filename") == dest.name:
|
||||
post_id = str(item.get("post_id") or "")
|
||||
media_id = str(item.get("media_id") or "")
|
||||
handle = str(item.get("handle") or "")
|
||||
break
|
||||
if not post_id and "_" in src.stem:
|
||||
parts = src.stem.split("_")
|
||||
post_id = parts[0]
|
||||
media_id = parts[1] if len(parts) > 1 else ""
|
||||
row = {
|
||||
"post_id": post_id,
|
||||
"media_id": media_id,
|
||||
"handle": handle,
|
||||
"role": "ocr",
|
||||
"filename": dest.name,
|
||||
"publish": False,
|
||||
"url": None,
|
||||
"embed": False,
|
||||
"source_filename": src.name,
|
||||
}
|
||||
items = [i for i in items if not (i.get("role") == "ocr" and i.get("source_filename") == src.name)]
|
||||
items.append(row)
|
||||
data["items"] = items
|
||||
media_json.write_text(json.dumps(data, indent=2) + "\n", encoding="utf-8")
|
||||
print(f"updated {media_json}")
|
||||
|
||||
|
||||
def main(argv: list[str] | None = None) -> int:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--in", dest="src", type=Path, required=True)
|
||||
parser.add_argument("--out", dest="dest", type=Path, default=None)
|
||||
parser.add_argument(
|
||||
"--engine",
|
||||
choices=("auto", "umi", "tesseract", "windows"),
|
||||
default="auto",
|
||||
)
|
||||
parser.add_argument("--media-json", type=Path, default=None)
|
||||
args = parser.parse_args(argv)
|
||||
|
||||
if not args.src.is_file():
|
||||
raise SystemExit(f"missing {args.src}")
|
||||
dest = args.dest
|
||||
if dest is None:
|
||||
dest = args.src.with_name(args.src.stem.replace("_orig", "") + "_ocr.txt")
|
||||
if dest.name == args.src.stem + "_ocr.txt" and args.src.stem.endswith("_orig"):
|
||||
dest = args.src.with_name(args.src.stem[: -len("_orig")] + "_ocr.txt")
|
||||
|
||||
engine = args.engine
|
||||
if engine == "auto":
|
||||
if find_umi():
|
||||
engine = "umi"
|
||||
elif find_tesseract():
|
||||
engine = "tesseract"
|
||||
else:
|
||||
engine = "windows"
|
||||
print(f"engine={engine}")
|
||||
if engine == "umi":
|
||||
run_umi(args.src, dest)
|
||||
elif engine == "tesseract":
|
||||
run_tesseract(args.src, dest)
|
||||
else:
|
||||
run_windows_ocr(args.src, dest)
|
||||
|
||||
text = dest.read_text(encoding="utf-8", errors="replace")
|
||||
print(f"wrote {dest} ({len(text)} chars)")
|
||||
if args.media_json:
|
||||
append_media_row(args.media_json, args.src, dest)
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
Reference in new issue
Block a user